Productivity · AI Workflow Management
Union.ai
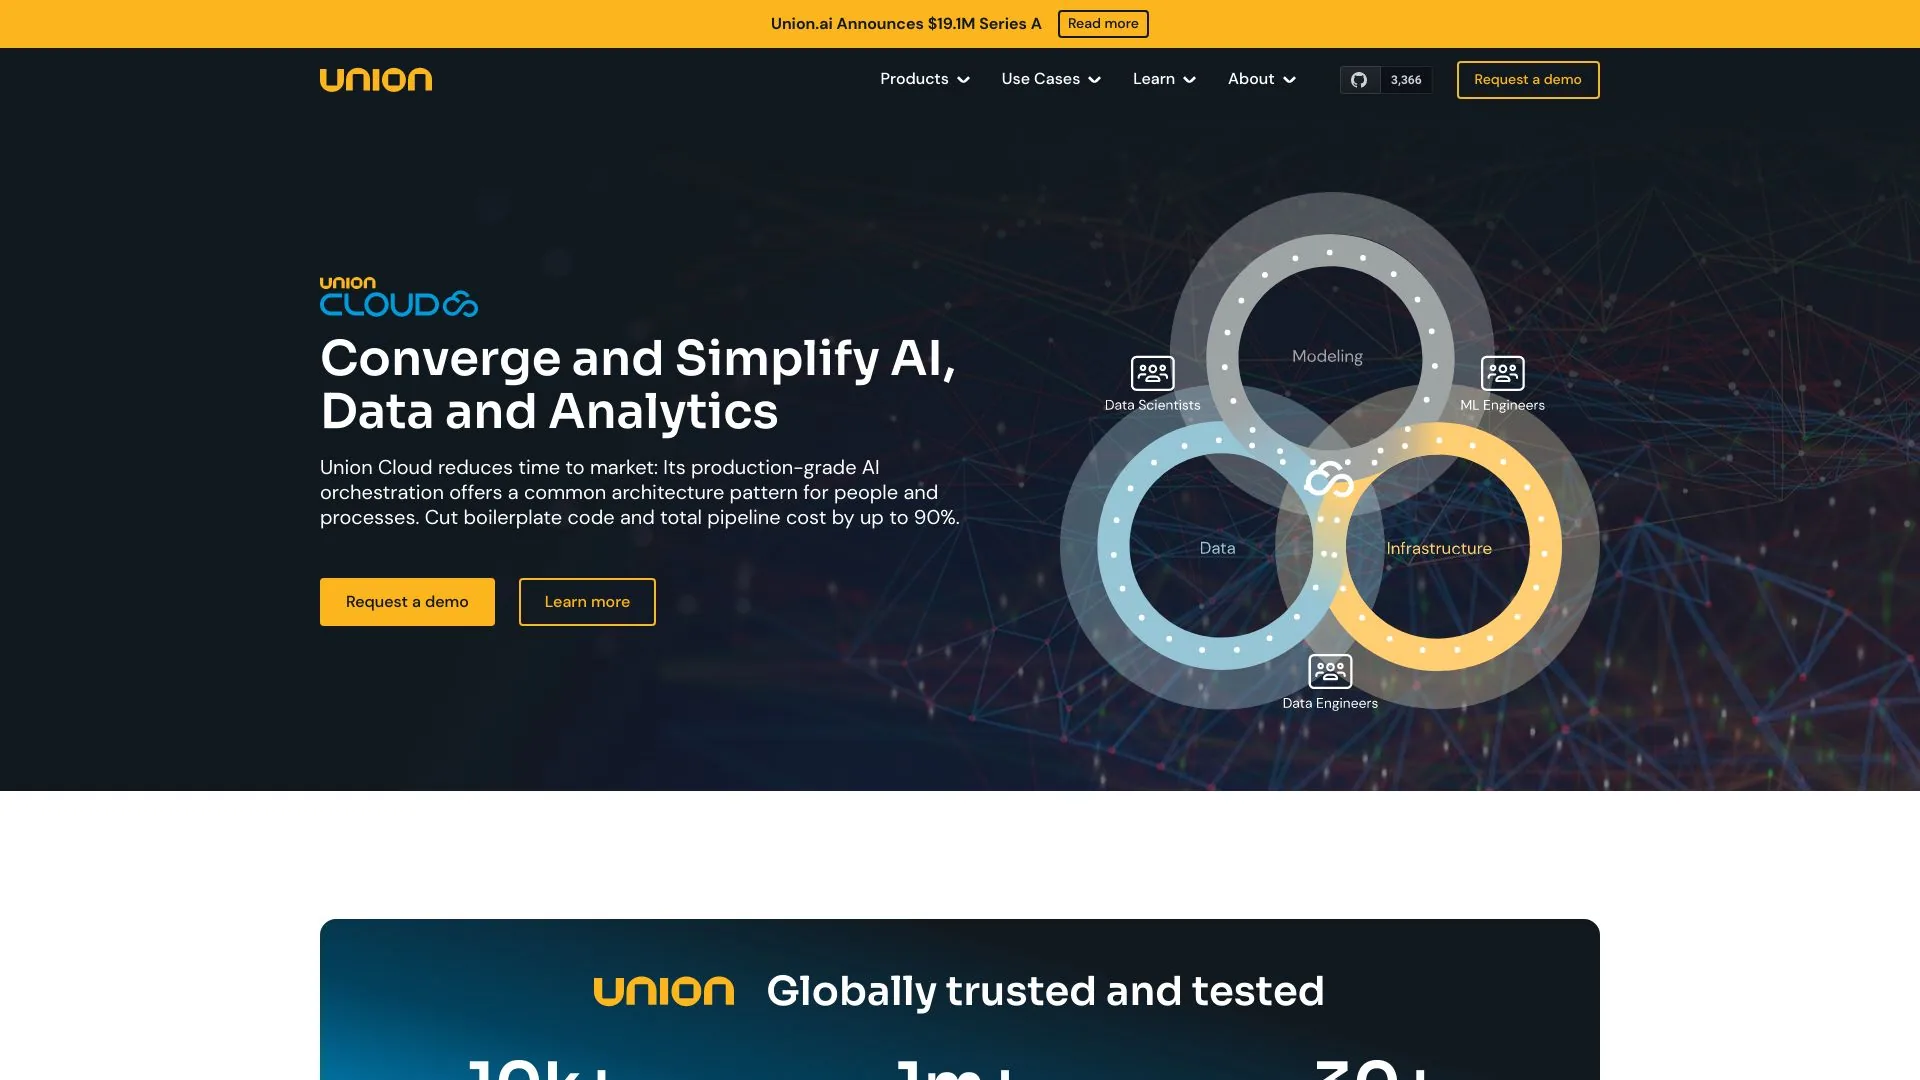
Union.ai simplifies AI, data and analytics, cutting costs and time to launch by 90%.
Open source
- Website
- union.ai
- Category
- Productivity › AI Workflow Management
- Pricing
- Open source
- Platforms
- website
30-day free trial Every plan starts free for 30 days. Sign up, run real workloads, pay nothing until day 31. | 30-day free trial | Every plan starts free for 30 days. | Sign up, run real workloads, pay nothing until day 31. | $950 / mo + usage 30-day free trial, then $950 minimum credited to usage monthly | $950 / mo + usage | / mo + usage | 30-day free trial, then $950 minimum credited to usage monthly
About Union.ai
Monthly credits. Predictable costs. No surprises. Union.ai self-service deployment is now available on AWS Marketplace. Sign up, run real workloads, pay nothing until day 31. For teams building AI from experiment to production. Published rate card, volume discounts applied automatically For organizations building mission-critical AI, ML, and agents. “Union.ai has been critical at the time that we needed to significantly scale up… Union.ai’s wealth of expertise has enabled us to move fast and deliver at scale.” You pay for what each action consumes: the action itself, plus the vCPU, memory and GPU it allocates, metered to the second. Every ladder is measured on the volume you use in a calendar month and starts again from the first band on the first of the next. Nothing carries over.
Screenshots
Reviews
““We can scale to 200,000–300,000 pods with the escalation logic baked right in, and the out-of-memory and scheduling headaches I used to fight are simply gone.””
““Our inference runs exceed the scale limits of a standard EKS cluster. With Union, we can have a single run span multiple clusters while having that single run spawn thousands of GPUs and call hundreds of thousands of actions, all of which are cached durably.””
““Rather than dealing with eight new AWS users and all the permissions, we just set up intern projects… Using Union for compute helps a ton because we're not setting up individual EC2 instances for each one of them.””
““Initially it was something like four minutes, because we were pulling every layer. Now if I look at the logs, it's always under one second. We never have any issue with cold starts.””
““Definitely easier to scale than Ray, since you have a lot more granular control over streaming the parallelism. The parallel async model is nice to work with.””